Mistral launched Large 4 this week, a mixture-of-experts model it says pushes the frontier of open-weight performance. Artificial Analysis, scoring the preview on October 6, put it at 38 on Intelligence Index v4.3.2 and called that the highest mark from outside the United States and China. Five Chinese open models still sit above it on the same index: DeepSeek V4.1 Flash at 39, GLM-5.3-Flash at 42, Kimi K3 at 44, GLM-5.3 at 45, and MiMo-V2.6-Pro at 46. Mistral says the weights arrive by the end of the month. Artificial Analysis lists the preview as proprietary until that release.
Tom's Hardware walked through the scorecard. MiMo-V2.6-Pro is in the same size class as Large 4. GLM-5.3-Flash is about a third as large, 320 billion parameters in total and 18 billion active, against 49 to 52 billion active for the Mistral model. DeepSeek is weighing a funding round of up to $15 billion. The index gap with its Flash model is a single point.
A benchmark task costs $1.13, or 13 cents
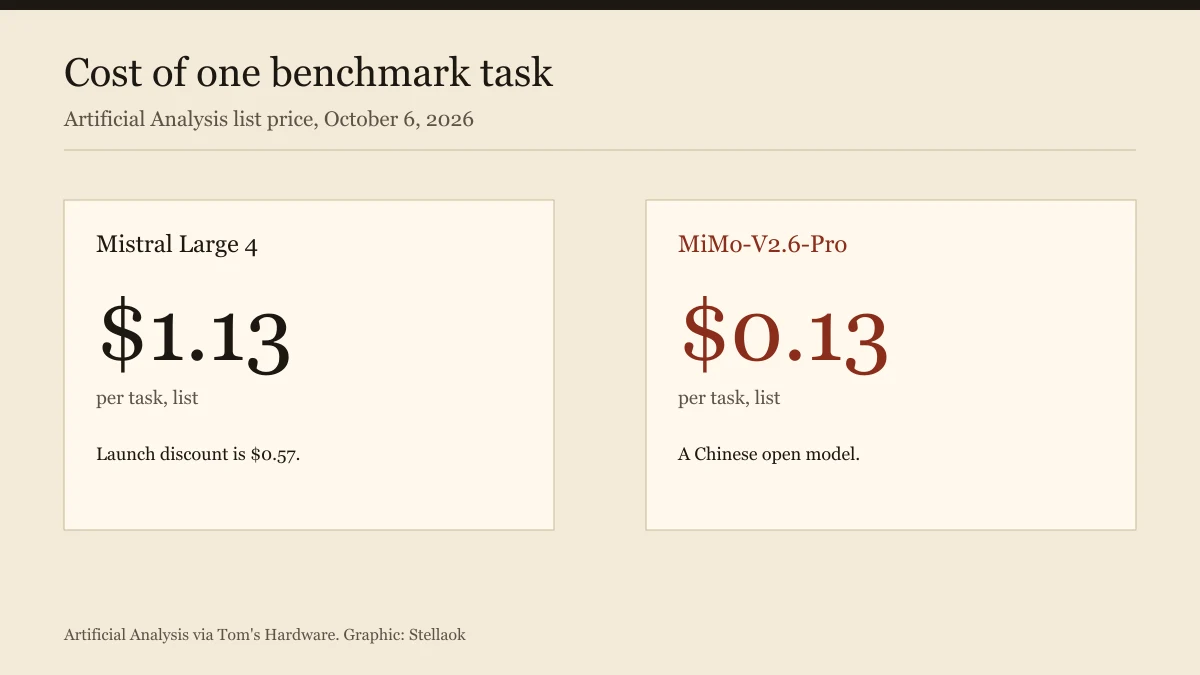
At list price, Large 4 runs $1.13 per Artificial Analysis task. A 50 percent launch discount takes that to $0.57. MiMo-V2.6-Pro is $0.13 on the same yardstick, and GLM-5.3-Flash is $0.25. The bill comes from volume. Running the index takes 200 million output tokens for Large 4, against a median of 81 million. Speed, measured on Mistral's own API, was 116.1 tokens a second, with 1.46 seconds to the first token. Artificial Analysis puts that about 33 percent above the tier median, and 2.6 times faster to the first token. Mistral says the API runs on the same hardware used to train the model. The discount lasts the first two weeks after release.
On one cyber test the ranking flips. Large 4 scored 81.7 percent on CyberGym-E2E-AA, which both firms describe as its strongest result, against 74 percent for GLM-5.3-Flash. That test is one of three in the Cyber Index. Large 4 scores 16 percent on DeepsecBench-AA and 51 percent on CWE-Bench-AA. Artificial Analysis projects that once the weights ship, the model will rank among the top three open-weight systems on the Cyber Index.
Closed models refuse the cyber test and match the index
Large 4 beats OpenAI's GPT-6 Luna on that CyberGym measure. Luna still matches the 38 on the intelligence index, at about $0.07 a task. Mistral says Claude Opus 5.5 and GPT-6 Astra score near zero on the same cyber test because they refuse the task, and Artificial Analysis marks both as declining some items on safety grounds. Chief executive Arthur Mensch, speaking in Abu Dhabi, told Reuters the model is above the Chinese models on certain aspects, including cyber.
Mistral's own sheet adds numbers the index does not. DeepSWE v1.1 at 61.7 percent, a Coding Agent Index at 49.8 percent, AutomationBench at 59.9 percent, and Dense 200 at 42 percent. Artificial Analysis puts Large 4 at 27 percent on Terminal-Bench 4.0. On the Coding Agent Index, Mistral says it beats DeepSeek V4 Pro 0813 and Qwen3.8 Max. The index-versus-cost chart places Large 4 below the Pareto line, just outside the quadrant Artificial Analysis labels most attractive. Huang has said Nvidia's chip sales will double next year. Large 4 was trained on that company's Grace Blackwell chips.
Training used 3,800 Grace Blackwell GPUs in Europe
Mistral says the model was trained from scratch on 3,800 Nvidia Grace Blackwell GPUs in the company's own European data centers, over roughly two months, a duration VentureBeat reported. Large 3, released last year, used 3,000 H200s and was smaller: 675 billion parameters in total, 41 billion active. The company describes a 3 billion euro Series D as the largest equity round a European technology firm has raised. Mistral Compute, announced with Nvidia last year, is planned around 18,000 Grace Blackwell chips. SoftBank paid 9.75 percent to fund its own AI spending, a debt price on a different continent from Mistral's equity round.
Artificial Analysis says the model may be scored again once someone other than Mistral can run the weights. Architecture details and further benchmarks are due with that release.